FreeBSD srcmgr@ has launched llm-postcr, an opt-in service that runs each src commit through an LLM (currently Claude) and reports bugs after the commit.
Opting in: run touch ${HOME}/.llm-postcr-opt-in on freefall. If your home directory isn’t readable by others, email srcmgr privately. Reports go to the committer if they’ve opted in, otherwise to srcmgr.
What it reports: only concrete, observable problems, not style(9) issues. It also flags pre-existing bugs in the code a commit touches, and fixing those is generally up to the committer. The exception is a commit that fixes some instances of a problem but misses others, where the missed ones should be addressed.
Results so far: after a couple of weeks of running with manual validation, it found about 100 new and 50 pre-existing bugs in the last 500 commits, with widely varying severity.
Limits: it doesn’t replace code review or testing.
Plans:
An opt-in pre-commit review service is in the works.
Reports are logged in a database and may become public later, for example in Bugzilla.
Claude Opus 4.6: Anthropic’s Most Capable Model Yet
Published February 6, 2026 — 8 min read
On February 5, 2026, Anthropic released Claude Opus 4.6 — its most powerful AI model to date. Arriving just three months after Opus 4.5, this update delivers a massive expansion to the context window, a new “agent teams” paradigm for parallel task execution, and benchmark scores that surpass both OpenAI’s GPT-5.2 and Google’s Gemini 3 Pro across a range of evaluations.
Whether you’re a developer building agentic workflows, a knowledge worker producing professional documents, or a researcher wrestling with enormous datasets, Opus 4.6 marks a tangible leap in what an AI model can handle in a single session.
1MToken context window (beta)
128KMax output tokens
68.8%ARC AGI 2 score
$5 / $25Input / output per 1M tokens
What’s New in Opus 4.6
While the version bump from 4.5 to 4.6 may seem incremental, the changes under the hood are substantial. Anthropic has focused on three pillars: reasoning depth, context capacity, and agentic execution.
⚡
1 Million Token Context Window A 5× increase over the previous 200K limit. Opus 4.6 scores 76% on the MRCR v2 needle-in-a-haystack benchmark at 1M tokens, compared to just 18.5% for Sonnet 4.5 — a qualitative shift in usable context.
🤖
Agent Teams in Claude Code Multiple specialised agents can now split a task and work in parallel — one on the frontend, one on the API, one on a migration — coordinating autonomously. Anthropic reports a roughly 30% reduction in end-to-end task runtime.
🧠
Adaptive Thinking Replaces the binary on/off extended thinking toggle. Opus 4.6 dynamically decides how much reasoning effort a prompt requires. Four effort levels (low, medium, high, max) give developers fine-grained cost–speed–quality control.
♾️
Context Compaction API A new beta feature that automatically summarises older context as conversations grow, enabling effectively infinite sessions without manual truncation or sliding-window hacks.
📊
Claude in PowerPoint & Excel Updates Claude now operates as a side panel inside PowerPoint, respecting your slide masters and layouts. Excel gets unstructured data support and longer workflows for paid subscribers.
Benchmark Breakdown
Opus 4.6 sets new state-of-the-art scores on several major evaluations. The most striking result is on ARC AGI 2, a benchmark designed to measure novel problem-solving that is easy for humans but notoriously hard for AI. Opus 4.6 scored 68.8% — nearly double Opus 4.5’s 37.6% and well ahead of GPT-5.2 (54.2%) and Gemini 3 Pro (45.1%).
Benchmark
Opus 4.6
Opus 4.5
GPT-5.2
Gemini 3 Pro
Terminal Bench 2.0
65.4%
59.8%
—
—
OSWorld (Agentic)
72.7%
66.3%
< 72.7%
< 72.7%
ARC AGI 2
68.8%
37.6%
54.2%
45.1%
MRCR v2 (1M ctx)
76%
—
—
—
Humanity’s Last Exam
#1
—
—
—
Beyond the headline numbers, Opus 4.6 also tops the GDPval-AA benchmark for economically valuable knowledge work, outperforming GPT-5.2 by approximately 144 ELO points. In life sciences, it delivers nearly twice the performance of its predecessor on computational biology, structural biology, organic chemistry, and phylogenetics tests.
Coding and Developer Impact
Coding has always been a strength of the Opus line, and 4.6 takes it further. The model plans more carefully before generating code, catches its own mistakes through improved self-review, and sustains agentic tasks for longer without losing coherence. For large codebases, Anthropic claims it can now handle autonomous code review, debugging, and refactoring across repositories that would have previously required human intervention.
“Opus 4.6 is a model that makes the shift from chatbot to genuine work partner really concrete for our users.”
— Scott White, Head of Product, Anthropic
The new agent teams feature in Claude Code is particularly noteworthy. Rather than a single agent working sequentially, developers can now spin up parallel agents that own distinct parts of a task. Anthropic’s example: one agent handles the frontend, another the API layer, and a third manages database migrations — all coordinating autonomously. This is available as a research preview and represents a meaningful step towards multi-agent orchestration out of the box.
Enterprise and Knowledge Work
Anthropic has been explicit about targeting enterprise workflows with this release. Roughly 80% of the company’s business comes from enterprise customers, and Opus 4.6 is tuned for the kind of work they care about: financial analysis, legal research, document production, and multi-step research tasks.
The model now leads on the Finance Agent benchmark and TaxEval by Vals AI. Combined with the expanded context window, analysts can feed entire filings, market reports, and internal data into a single session and get coherent, cross-referenced outputs. Anthropic says Opus 4.6 produces documents, spreadsheets, and presentations that approach expert-created quality on the first pass, reducing the rework cycle significantly.
💡 Pricing NoteStandard API pricing remains at $5 input / $25 output per million tokens — identical to Opus 4.5. Requests exceeding 200K input tokens are charged at a premium rate of $10 / $37.50 per MTok. The model is available via the Anthropic API, AWS Bedrock, Google Vertex AI, Microsoft Foundry, and directly on claude.ai.
Availability and API Changes
Opus 4.6 is live now across all major platforms. The API model identifier is simply claude-opus-4-6 — note the simplified naming without a date suffix. It’s available on the Anthropic API, AWS Bedrock, Google Vertex AI, Microsoft Foundry, and through GitHub Copilot for Pro, Pro+, Business, and Enterprise users.
Developers should be aware of a few breaking changes: assistant message prefilling now returns a 400 error (migrate to structured outputs or system prompt instructions), the output_format parameter has moved to output_config.format, and the effort parameter is now generally available without a beta header.
Safety and Alignment
Anthropic reports that the intelligence gains in Opus 4.6 have not come at the cost of safety. On their automated behavioural audit, the model showed low rates of misaligned behaviours including deception, sycophancy, and encouragement of user delusions — matching Opus 4.5’s results. Six new cybersecurity probes have been added to evaluate potential misuse vectors, and the model achieves a lower rate of unnecessary refusals compared to previous releases.
The Bigger Picture
Opus 4.6 arrives at a moment of intensifying competition. OpenAI announced its new OpenAI Frontier enterprise platform just hours before Anthropic’s launch, signalling a strategic pivot towards infrastructure and agent management rather than competing purely on benchmark scores. Google’s Gemini 3 Pro and Microsoft’s deep integration of Opus 4.6 into Foundry add further complexity to the landscape.
What sets this release apart is the combination of raw capability and practical utility. The 1M context window, agent teams, adaptive thinking, and context compaction aren’t just benchmark optimisations — they address real friction points that developers and knowledge workers hit daily. If Opus 4.5 moved Claude from “chatbot” to “useful tool,” Opus 4.6 positions it as a genuine work partner that can own entire workflows end-to-end.
For those already running Opus 4.5 in production, the upgrade path is a single API version change at the same price point. For everyone else, this is a strong argument to take a serious look at what Claude can do in 2026.
Immich, the popular open-source, self-hosted photo and video management solution, has launched a community-driven initiative to improve its metadata handling capabilities. Through the new EXIF Dataset project, users can contribute their photos to help train and improve Immich’s EXIF parsing and metadata extraction features.
I recently contributed some of my own photos to the project, and I want to share how easy and straightforward the process is. If you’re an Immich user (or simply an open-source enthusiast), this is a fantastic way to give back to the community.
What is the EXIF Dataset Project?
EXIF (Exchangeable Image File Format) data is the metadata embedded in your photos by your camera or smartphone. This includes information like the camera make and model, date and time, GPS coordinates, lens information, and much more. Immich uses this data extensively to organize your photo library, enable timeline views, power location-based features, and facilitate powerful search capabilities.
The EXIF Dataset project at datasets.immich.app/projects/exif allows community members to contribute photos along with their intact EXIF metadata. This crowdsourced dataset helps the Immich team understand how different cameras and devices encode their metadata, ultimately improving compatibility and parsing accuracy for everyone.
The contribution process is remarkably simple and well-designed. Here’s how it works:
Step 1: Upload Your Photos
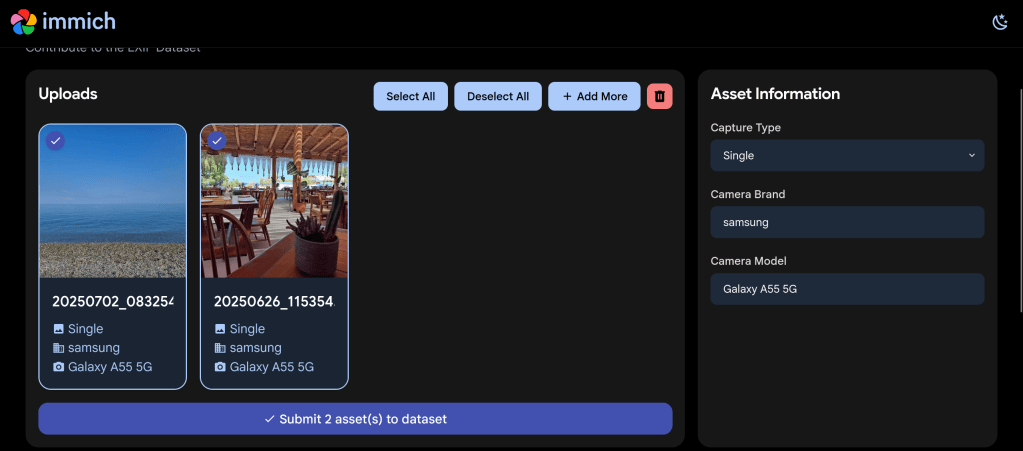
After navigating to the EXIF Dataset project page, you’re greeted with a clean upload interface. I uploaded a couple of photos taken with my Samsung Galaxy A55 5G – a beach landscape shot and a photo from a beachside restaurant.
The clean upload interface showing my first selected photo with its EXIF metadata displayed
The interface immediately displays the extracted EXIF information on the right side, including the capture type (Single), camera brand (Samsung), and camera model (Galaxy A55 5G). This lets you verify that your photos contain the metadata you want to contribute.
Step 2: Select Photos for Submission
You can upload multiple photos at once using the “+ Add More” button. I selected both of my photos for contribution – each showing clearly with a checkmark indicating selection.
Two photos selected and ready to submit to the EXIF Dataset
The interface provides convenient “Select All” and “Deselect All” buttons, as well as a delete option if you change your mind about any uploads.
Step 3: Agree to the CC0 License
When you click “Submit asset(s) to dataset”, a Dataset Agreement dialog appears. This is where the legal side of your contribution is handled transparently.
The Dataset Agreement confirms your photos will be released under the CC0 public domain license
ℹ️ About CC0: The CC0 (Creative Commons Zero) license means you’re releasing your contributed photos into the public domain. This allows the Immich project (and anyone else) to use the images freely for any purpose. Make sure you only upload photos you own the rights to and are comfortable sharing publicly.
The agreement requires you to confirm two things:
You agree to release the uploaded assets under the CC0 license into the public domain
The files have not been modified in any way that would alter their original content or metadata
You also provide a contact email in case the Immich team has any questions about your upload.
Why Should You Contribute?
Contributing to the EXIF Dataset helps improve Immich in several ways:
Better Device Support: By collecting EXIF samples from many different cameras and phones, Immich can improve its parsing for devices that may have quirks or non-standard metadata encoding
Improved Metadata Extraction: The dataset helps identify edge cases and unusual metadata formats that might otherwise go unnoticed
Community-Driven Development: Your contribution directly influences the quality of an open-source project used by thousands of self-hosters worldwide
Supporting Privacy-Focused Software: Immich is a privacy-respecting alternative to cloud-based photo services like Google Photos – your contribution helps make it even better
Tips for Contributing
To make your contribution as valuable as possible:
Contribute from different devices: If you have photos from older cameras, different smartphone brands, or professional equipment, these are especially valuable
Keep metadata intact: Don’t strip or modify the EXIF data before uploading – the original metadata is exactly what’s needed
Consider variety: Photos taken in different conditions (indoor, outdoor, various lighting) may contain different metadata values
Check your ownership: Only contribute photos you’ve taken yourself or have explicit rights to share
About Immich
For those unfamiliar with Immich, it’s a high-performance, self-hosted photo and video management solution that offers features comparable to Google Photos – but with full control over your data. Key features include automatic backup from mobile devices, facial recognition, smart search, timeline views, shared albums, and much more.
Immich is developed under the AGPL-3.0 license and is backed by FUTO, an organization dedicated to developing privacy-preserving technology. The project has grown tremendously, with over 77,000 stars on GitHub, making it one of the most popular self-hosted applications available.
🏠 Self-Host Immich: Get started with Immich at immich.app – available for Docker, TrueNAS, Unraid, and other platforms.
Conclusion
Contributing to the Immich EXIF Dataset is a simple yet meaningful way to support open-source software development. The process takes just a few minutes, and your contribution will help improve photo management for the entire Immich community.
GitHub has officially rolled out the improved “Files Changed” experience as the default for all users. After months in public preview, this redesigned pull request review interface brings significant improvements to performance, accessibility, and overall productivity when reviewing code changes.
Key Improvements Over the Classic Experience
The new interface maintains familiarity for existing users while adding several notable enhancements:
Comment on Any Line
Previously, you could only comment on lines directly surrounding a change. Now you can add review comments to any line in a changed file, making it easier to provide context or point out related code that might need attention.
View PR Description Without Switching Pages
A new Overview panel lets you view the pull request description directly from the “Files changed” page. No more jumping back and forth between tabs to remember what the PR is supposed to accomplish.
Enhanced File Tree
The file tree sidebar is now resizable and includes visual indicators showing which files have comments, errors, or warnings. This makes it much easier to track your progress when reviewing large PRs with many changed files.
Draft Comments That Persist
Comments and replies are now saved locally in your browser. If you accidentally close the tab or refresh the page, your in-progress feedback won’t be lost.
Fewer Page Reloads
Actions like refreshing to pull in new changes, switching between split and unified diff modes, and other common tasks no longer force a full page reload. The interface feels much snappier as a result.
Improved Accessibility
The new experience includes better keyboard navigation, screen reader landmarks, and increased line spacing options to make code review accessible to everyone.
Experimental Mode for Large Pull Requests
One of the most interesting additions is an experimental mode specifically designed for reviewing large pull requests. This mode uses virtualization to reduce the number of DOM elements the browser needs to manage, significantly improving memory usage and page responsiveness—especially on slower machines.
When viewing a large PR, you’ll see a banner offering to try this experimental mode. There are some trade-offs: browser find functionality, text selection across the entire page, printing, and some browser extensions may not work as expected since the full diff isn’t rendered in the DOM. You can switch back to single file mode at any time.
Bug Fixes and Polish
GitHub has also addressed numerous issues including problems with suggested changes being applied incorrectly, comment workflow bugs, interaction lag (especially on Safari), and various UI quirks like scroll positioning and sticky headers behaving unexpectedly.
Opting Out
If you prefer the classic experience, you can still opt out through your settings. However, given the improvements in this new version, it’s worth giving it a fair trial before switching back.
Providing Feedback
GitHub is actively collecting feedback on the new experience. If you encounter issues or have suggestions, you can participate in the “Files Changed” preview feedback discussion on GitHub.
I’ve released anki-snapshot, a tool that brings proper version control to your Anki flashcard collection. Every change to your notes is tracked in git, giving you full history, searchable diffs, and the ability to see exactly what changed and when.
The Problem
Anki’s built-in backup system saves complete snapshots of your database, but it doesn’t tell you what changed. If you accidentally delete a note, modify a card incorrectly, or want to see how your deck evolved over time, you’re stuck comparing opaque database files.
The Solution
anki-snapshot exports your Anki collection to human-readable text files and commits them to a git repository. This means you get:
Full history: See every change ever made to your collection
Meaningful diffs: View exactly which notes were added, modified, or deleted
Search through time: Find when a specific term appeared or disappeared
Easy recovery: Restore individual notes from any point in history
How It Works
The tool reads your Anki SQLite database and exports notes and cards to pipe-delimited text files. These files are tracked in git, so each time you run anki-snapshot, any changes are committed with a timestamp.
~/anki-snapshot/
├── .git/
├── notes.txt      # All notes: id|model|fields...
├── cards.txt      # All cards: id|note_id|deck|type|queue|due|ivl...
└── decks.txt      # Deck information
Commands
Command
Description
anki-snapshot
Export current state and commit to git
anki-diff
Show changes since last snapshot
anki-log
Show commit history with stats
anki-search "term"
Search current notes for a term
anki-search "term" --history
Search through all git history
anki-restore <commit> <note_id>
Restore a specific note from history
Example: Tracking Changes
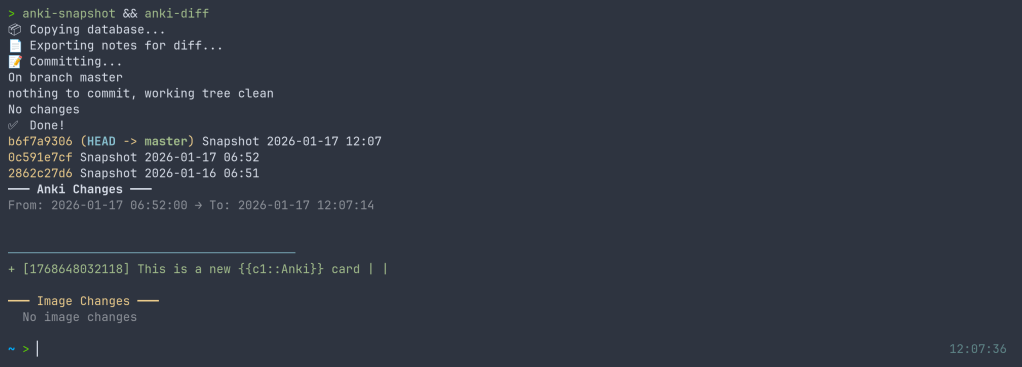
After editing some cards in Anki, run the snapshot and see what changed:
$ anki-snapshot
[main a3f2b1c] Snapshot 2026-01-14 21:30:45
 1 file changed, 3 insertions(+), 1 deletion(-)

$ anki-diff
━━━ Changes since last snapshot ━━━

Modified notes: 2
+ [1462223862805] Which antibodies are associated with Hashimoto...
− [1462223862805] Which antibodies are associated with Hashimoto...

New notes: 1
+ [1767170915030] Germline polymorphisms of the ATPase 6 gene...
Example: Searching History
Find when “mitochondria” was added or modified across your entire collection history:
$ anki-search "mitochondria" --history

commit e183cea7b3e36ad8b8faf7ca9d5eb8ca44d5bb5e
Date:   Tue Jan 13 22:43:47 2026 +0100
+ [1469146863262] If a disease has a mitochondrial inheritance pattern...
+ [1469146878242] Mitochondrial diseases often demonstrate variable expression...

commit 41c25a53471fc72a520d2683bd3defd6c0d92a88
Date:   Tue Jan 13 22:34:48 2026 +0100
− [1469146863262] If a disease has a mitochondrial inheritance pattern...
Integration with Anki
For seamless integration, you can hook the snapshot into your Anki workflow. I use a wrapper script that runs the snapshot automatically when closing Anki:
$ anki-wrapper # Opens Anki, snapshots on close
Or add it to your shell aliases to run before building/syncing your deck.
Installation
The tool is available on the AUR for Arch Linux users:
yay -S anki-snapshot
Or install manually:
git clone https://github.com/chrislongros/anki-snapshot-tool
cd anki-snapshot-tool
./install.sh
Requires: bash, git, sqlite3
Why Not Just Use Anki’s Backups?
Anki’s backups are great for disaster recovery, but they’re binary blobs. You can’t:
See what changed between two backups without restoring them
Search for when specific content was added
Selectively restore individual notes
Track your collection’s evolution over months or years
With git-based snapshots, your entire editing history becomes searchable, diffable, and recoverable.